



Strata is a notebook your coding agent can drive, and everything it computes stays.
Coding agents explore by writing throwaway scripts: python -c, files in
/tmp, invisible and gone by the next session. Point one at Strata and the
work lands in a notebook instead. Every result is cached by what produced it,
every cell records who wrote it, and the whole thing is open in your browser
while the agent works. Come back tomorrow and it is all still there, already
computed.
That holds because of what a cell is. Each one is keyed by its source, its inputs and its environment, so the expensive step an agent ran ten turns ago is a cache hit now, and the same inputs give the same result a year later on another machine. Change one cell and only the cells below it run again. Nothing is recomputed to prove a point.
It is a good notebook for a person, too. Ask a model a question in a prompt
cell and the answer is cached like any other result. Send the slow cell to a
GPU with one line. Read an S3 prefix as a local path. The notebook itself is
plain .py files plus a manifest, so a commit is a readable diff rather than
a wall of JSON.

Docs: bearing-research.github.io/strata
Install it as a one-command Claude Code plugin
(needs the strata CLI on PATH; uv tool install "strata-notebook[mcp,tui]"):
/plugin marketplace add bearing-research/strata
/plugin install strata-scratchpad@strata
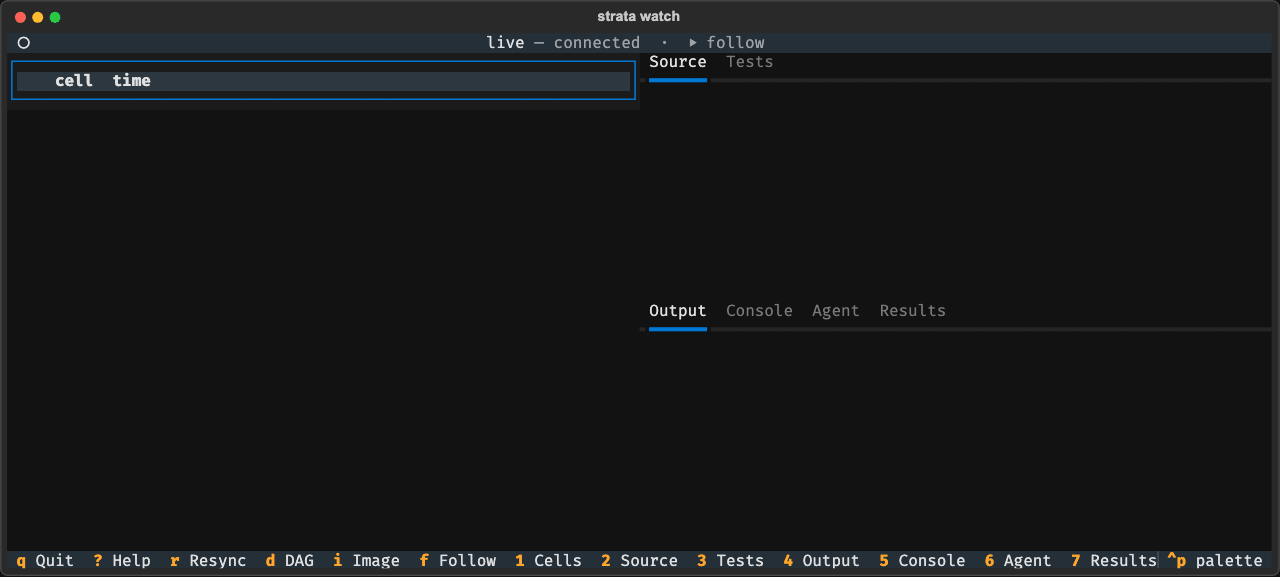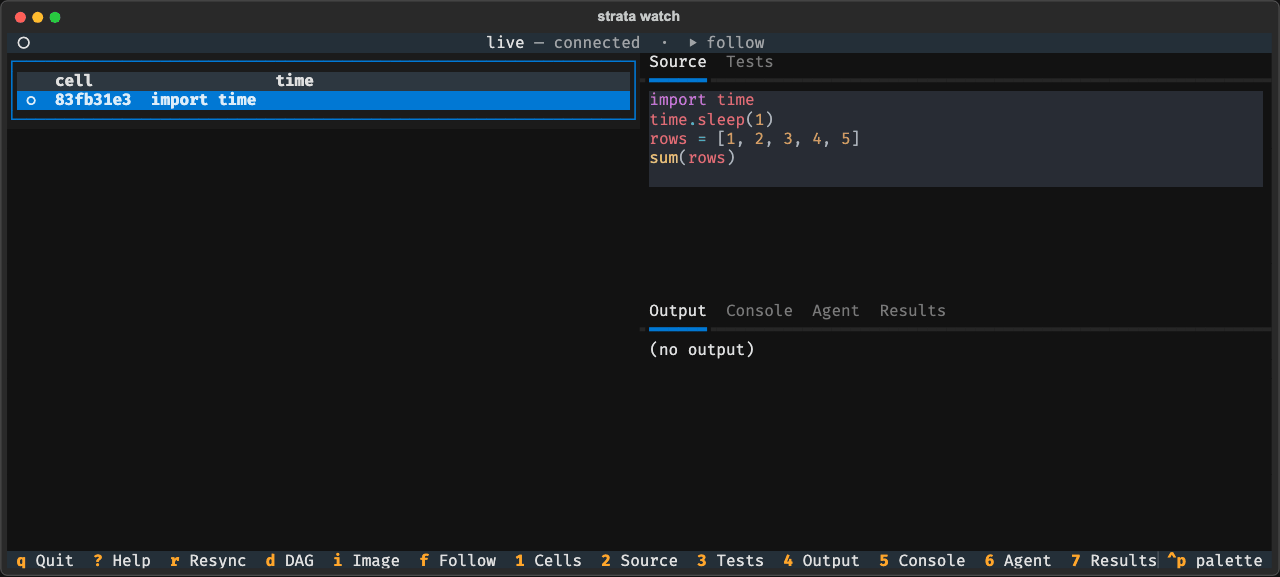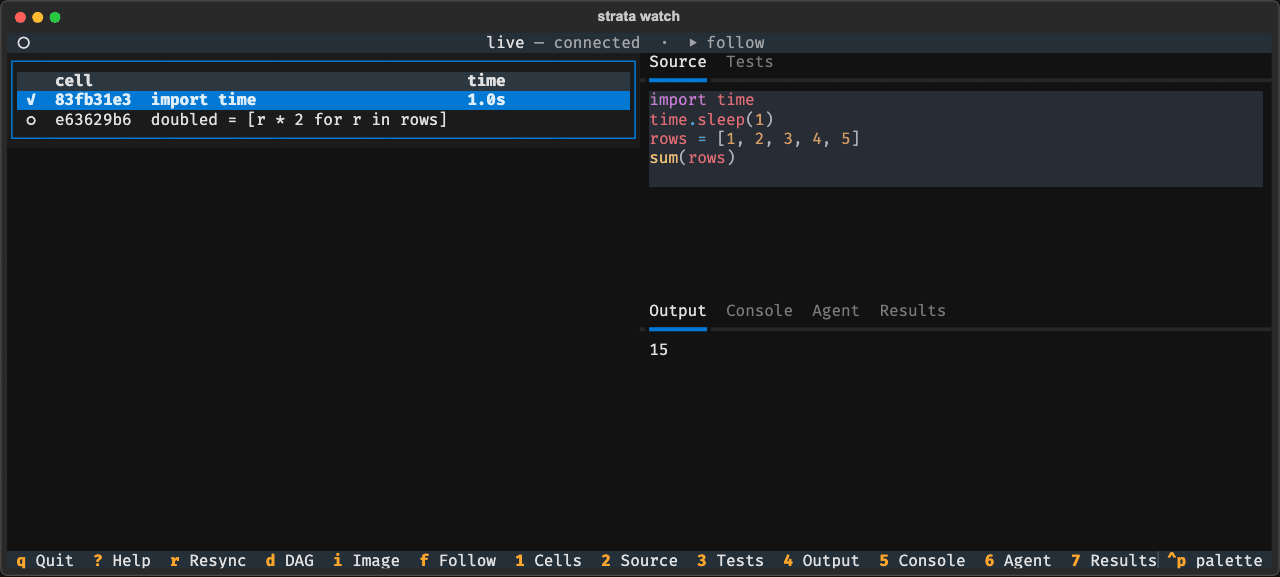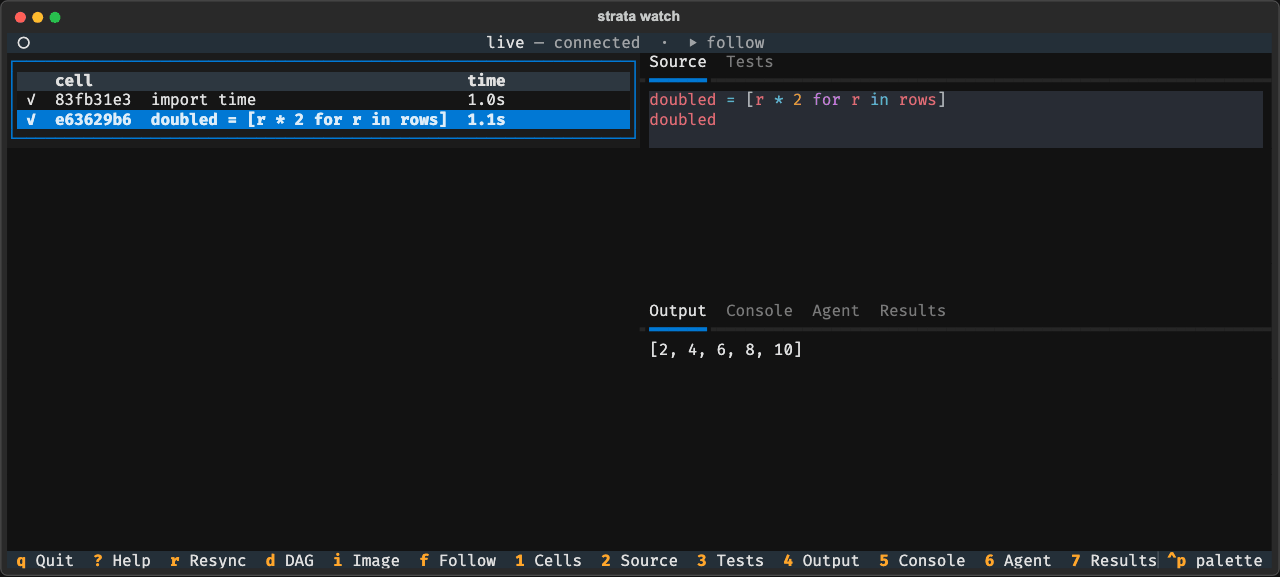
A coding agent drives the notebook in one terminal; strata-notebook-tui
mirrors it live in another. Captured from a real run, not a mock-up.
Whether an agent reaches for it instead of a scratch script is measured rather
than assumed. evals/agent_notebook/ drives the real on-ramp and grades the
result: 9 transcript-backed tasks run in CI, and a scratchpad group probes
whether an un-primed session uses the notebook at all. See
Driving a notebook with a coding agent.
For an agent
- a scratchpad that lasts: a Claude Code plugin points an agent at a cached notebook cell instead of a
/tmpscript, so the snippet it ran ten turns ago is still there - any MCP client: a warm notebook session is exposed at
/mcp, and you can watch the agent work in the browser or the terminal while it does - built to be scripted:
stratainspects, runs and authors a notebook with JSON output and stable exit codes, offline or against a live session - one command to start:
strata agent ./nbstands up the server, the session, the config and the viewer together - you can tell who did what: every cell records whether a person or an agent wrote it
Why nothing runs twice
- results are keyed by what made them: a cell's source, its inputs and its environment decide its identity, so identical work is a cache hit and no result ever needs invalidating
- only what changed re-runs: edit one cell and Strata re-runs the cells below it and nothing else
- no wiring: Strata reads each cell to find what it uses and what it defines, so there are no decorators and no edges to maintain by hand
- readable in git: a notebook is plain
.pyfiles plus a TOML manifest, so a diff shows the code that changed - the graph is visible: the dependency graph renders beside the cells, and double-clicking a node jumps to its source
Cell types
- prompt cells: LLM calls as DAG nodes,
{{ variable }}interpolation from upstream, cached by template + inputs + model config - SQL cells: named connections and bind-parameter templating, with drivers for DuckDB, SQLite, Postgres, Snowflake and BigQuery
- R cells: Python and R share one DAG, exchanging Arrow, so a
pandas.DataFrameis adata.framefor the next cell - loop cells:
# @loop max_iter=N carry=stateiterates with an explicit carry, each step its own artifact - variant sweeps: run every variant of a group and hand the downstream cell a
{name: value}dict, or fan out with# @per_variantso adding a variant only runs the new one - widget cells: declarative controls that downstream cells consume as inputs; with Live on, dragging one recomputes what depends on it
- cell unit tests: a Tests panel runs real pytest against a cell's defs and upstream inputs, doubling as a health badge
Compute and data
- distributed:
# @worker gpu-flydispatches a cell to a remote box; bring your own compute - worker pool (separate package,
pip install strata-pool): machines (Fly, Docker or RunPod) start on demand, are held for a tenant, hand out GPUs per cell, and stop when the work does - the same environment, elsewhere: a remote cell runs in the notebook's own locked environment rather than whatever the worker image holds
- the machine starts before the run: focusing a cell bound to a pooled worker, or starting Run All, asks the pool to bring up a machine while you are still reading the code
- remote cells over SSH: hand an agent an SSH target and it provisions a worker there, tunnels to it, and routes heavy cells over, cached like everything else
- workers behind NAT:
strata-worker --connectdials out to a relay, so a machine with no open port serves cells - lake-aware SQL: read a named catalog and the notebook's mounts in one query, pinned to the snapshot the cell's provenance records
- Iceberg as other engines write it: scans apply merge-on-read deletes and follow schema changes by field id, so tables Spark, Flink and DuckDB write read correctly, from SQL, REST, Glue, GCS and Azure catalogs
- every input recorded:
# @fetchmakes bytes from a URL an input,# @datasetmakes a registry name one, both content-addressed - mounts:
# @mount data s3://bucket/prefix romakes any S3, GCS or Azure prefix a localpathlib.Path - isolated envs: every notebook gets its own uv-managed
.venv/, locked and reproducible - headless:
strata run ./my-notebookfor CI and scheduled execution, same DAG and same cache
Teams
- promote to the team:
strata artifact promotecopies a result and the chain behind it into the team's store, from the notebook, the CLI or inside a cell - a colleague's run counts: a cell can be served from a teammate's earlier result: the expensive middle of a pipeline, not only what someone chose to name
- a figure gets a URL: publish an artifact and anyone with the link sees the plot, the code, and the environment of every step behind it, with no account and no install
- a notebook travels: export the whole state as one bundle and import it back, artifacts included
- share a session: presence, cell focus and soft locks, with every cell recording who wrote it
- safe to share (in service mode): cells run as their own OS user once you name one, notebook scopes are enforced on every notebook route under principal auth, and an MCP tool call runs as its caller
- host it for many people: in service mode every notebook route, the WebSocket and MCP stay within the caller's tenant, the server runs under a path behind your proxy, and the editor can be framed inside your own product
- a store that stays bounded: results nobody has used for a while are collected least recently used first, never anything named, pinned, published or still needed
Surfaces
- terminal viewer:
strata watchrenders a running notebook live in the terminal, read-only, over SSH or beside your editor - stop a run from anywhere: cancel a running cell from the browser,
strata cell cancel, REST or MCP, and on Linux and macOS a cell stops when the server that started it does - app view: open a notebook as a read-only app, embed it as an
<iframe>, or export a self-contained snapshot - data viewer: DataFrame outputs render in a grid you can page, sort, filter and search, backed by the full artifact rather than a preview
- also a library:
pip install strata-clienttalks to the store from any pipeline or service, with no server install - production: Iceberg-aware scans, trusted-proxy auth, multi-tenancy, and S3, GCS, Azure or local blob backends
Both paths below run in personal mode: single-user, writes enabled, no proxy auth. For multi-tenant or hosted deployments, see Deployment Modes.
# Docker. docker-compose.yml sets personal mode for you.
docker compose up -d --build
# Then open http://localhost:8765

# Or the prebuilt image (linux/amd64), published with each release.
docker run --rm -p 127.0.0.1:8765:8765 -v strata_state:/home/strata/.strata \
  ghcr.io/bearing-research/strata:0.10.0

# Or install via uv (recommended). Puts the CLI on PATH in a uv-managed
# tool env. `pip install` is not supported; see Requirements below.
# The mcp and tui extras are what `strata agent` and `strata watch` need.
uv tool install "strata-notebook[mcp,tui]"
strata-notebook
# Then open http://localhost:8765
For the full inventory of installed commands (strata-notebook, strata,
strata-worker, python -m strata), see the
Commands reference.
Source builds (git clone + uv sync) are documented in
Installation.
uv 0.8 or newer, and nothing else. uv fetches a matching Python for you.
Strata runs only inside a uv-managed environment. It checks for the
uv = <version> marker uv writes to pyvenv.cfg, which uv tool install,
uv add and uv run all produce and a hand-rolled python -m venv does not.
The reason is that the notebook subsystem shells out to uv to manage
per-notebook .venv/ directories; failing at startup with a clear message
beats a confusing subprocess error later. Conda and pip-venv users install uv
and run uv tool install strata-notebook, which builds its own env and leaves
existing data and environments untouched.
Windows: uv tool install strata-notebook works directly.
Building Strata itself from a git clone also needs Node 26+ for the frontend. The PyPI wheel ships it prebuilt, so this applies only if you are modifying Strata. Source builds work on Windows via WSL2 or natively.
Every notebook platform re-executes from scratch when you change one cell. Strata doesn't. The artifact store deduplicates by provenance hash. If the code and inputs haven't changed, the result is served instantly.
First run:     load data (10s) → clean (3s) → train (20s) → evaluate (1s)  = 34s
Change model:  load data (✓)   → clean (✓)  → train (20s) → evaluate (1s)  = 21s
Re-run:        load data (✓)   → clean (✓)  → train (✓)   → evaluate (✓)   = <1s
This is the architecture, not a layer on top of it. Every cell execution is a
materialize(inputs, transform, environment) → artifact operation, and the
cache is keyed on content rather than time, so it is correct by construction.
Even a leaf cell that only prints is cached: its console output is keyed
by the same provenance hash, so an unchanged re-run replays the output
instantly rather than executing again. That makes the notebook a good
scratchpad - a coding agent's exploratory snippets stop recomputing.
Cells that must always run (a side effect, a live API call, a fresh random
draw) opt out with # @nocache.
Each cell can declare which worker it runs on via a single annotation:
# @worker my-gpu
embeddings = model.encode(abstracts, batch_size=256)
You define workers in notebook.toml. Each one points at an HTTP
endpoint that implements the Strata executor protocol. A worker can be
a GPU box on RunPod, a DataFusion cluster on Fly, a beefy EC2 instance,
or anything else that speaks HTTP. The notebook routes the cell to the
declared worker at execution time, and the UI shows a live
dispatching → my-gpu badge while it runs.
No deployment code, no infrastructure glue. Bring your own compute, one annotation per cell.
Every piece of per-cell metadata is a comment directive in the cell's source. The source is the single canonical place for cell config: annotations always win over any stored defaults.
# @name Extract embeddings
# @worker gpu-fly
# @timeout 600
# @env MODEL_PATH=/models/bge-large
# @mount dataset s3://corpus/2024-q4 ro
embeddings = model.encode(dataset / "abstracts.jsonl")
Diagnostics fire on open, reload, and after an edit settles, for example
worker_unknown, mount_uri_unsupported, mount_shadows_notebook,
timeout_not_numeric, env_malformed. They surface as a pill in the
cell header and log structured warnings for headless runs.
Mounts bind a remote URI to a local path inside the cell. Supported
schemes: file://, s3://, gs://, az://. Credentials flow through
fsspec options: set anon = true for public buckets, or drop it to
use the standard credential chain.
[[mounts]]
name = "taxi_zones"
uri = "s3://nyc-tlc/misc"
mode = "ro"
options = { anon = true }
Inside the cell, taxi_zones is a pathlib.Path. Strata mirrors the
remote prefix to a local cache before the cell runs, and reuses that copy
while the remote fingerprint is unchanged. The mirror runs in Strata's own
environment, so install the extra for the scheme there: s3, gcs or
azure (for example uv tool install "strata-notebook[s3]").
| Example | What it shows |
|---|---|
| pandas_basics | Linear DataFrame chain, caching, staleness propagation, per-cell unit tests |
| iris_classification | End-to-end ML, DAG branching, mixed output types |
| titanic_ml | Feature engineering + model comparison |
| s3_mount | Reading a public S3 bucket via a mount |
| arxiv_classifier | Distributed execution via @worker + Modal GPU + Fly cluster |
| markdown_showcase | Markdown cells, dynamic Markdown(...) outputs, security cases |
| library_cells | Cross-cell library code: pure module cells, mixed runtime+library cells, the limits |
| news_alpha_trader | Multi-stage trading pipeline with prompt cells and structured LLM outputs |
| review_triage | Prompt cell with # @output_schema - structured, schema-validated LLM output |
| r_mtcars_analysis | Pure-R notebook - mtcars regression with inline ggplot2 / base-graphics plots |
| r_lm_vs_sklearn | Cross-language R + Python - R lm() vs scikit-learn over shared Arrow data |
| sql_orders_report | SQL cells over a local SQLite warehouse, mixing SQL / Python / markdown |
| widget_playground | Widget cell (control panel) driving a downstream cell, with # @live reactivity |
| model_variants | Variant groups - alternative training cells sharing one DAG slot (switch mode) |
| model_variants_sweep | Variant sweep mode - run every variant and compare them in one downstream cell |
| loop_hill_climb | # @loop / # @loop_until iteration with carry and per-iteration artifacts |
| data_viewer | Interactive data viewer - page / sort / filter / search the full cached artifact |
| agent_demo | A coding agent builds the notebook live; only the eval re-runs when the model caches |
Materialization, the artifact store, the DAG, caching and headless run are settled and covered by tests. Three surfaces are not:
- Prompt-cell API. Streaming, conversation memory and structured-output validation will change.
- SQL cloud drivers. DuckDB, SQLite and PostgreSQL run in CI. BigQuery and Snowflake ship without integration coverage. MotherDuck and MySQL are not implemented.
- On-disk formats.
notebook.toml,.strata/runtime.jsonand the artifact cache layout may change between minor versions. Depend on the Python API, not the file shapes.
Strata's HTTP API exposes the materialization layer directly,
driveable from Python via StrataClient. Useful for direct table
scans, custom transforms, and headless workflows; the notebook
executor is a separate pipeline that writes to the same artifact
store. The client talks to a running Strata server, so this workflow
has two steps: start the server, then call it from your code.
# 1. Install + start the server (in a uv-managed env).
uv tool install strata-notebook
strata-notebook

# 2. In your own project, install the slim client - a separate package
#    (httpx + pyarrow only, no server deps, plain pip is fine) - and
#    point it at the running server:
pip install strata-client
from strata_client import StrataClient
client = StrataClient(base_url="http://localhost:8765")
artifact = client.materialize(
inputs=["file:///warehouse#db.events"],
transform={"executor": "scan@v1", "params": {"columns": ["id", "value"]}},
)
table = client.fetch(artifact.uri) # Arrow table, cached by provenanceA result never goes stale, but an unnamed one is a cache entry: the server
keeps it while it is used, and its retention sweep (in personal mode, 30 idle
days or a 20 GiB store cap) may collect it later, after which the same call
computes it again. Name it (name= on materialize) or pin it to keep it. See
retention.
The server provides: provenance-based deduplication, immutable versioned artifacts, lineage tracking, Iceberg table scanning with row-group caching, pluggable blob storage (local/S3/GCS/Azure), multi-tenancy, trusted-proxy auth, and an executor protocol for external compute.
┌─────────────────────────────────────────────┐
│ Notebook UI (Vue.js + WebSocket)            │
│ cells, DAG view, workers                    │
└─────────────────────────────────────────────┘
                    │
                    ▼
┌─────────────────────────────────────────────┐
│ Notebook Backend (FastAPI)                  │
│ session, cascade, executor, prompt cells    │
└─────────────────────────────────────────────┘
                    │
                    ▼
┌─────────────────────────────────────────────┐
│ Strata Core                                 │
│ materialize, artifacts, lineage, dedupe     │
└─────────────────────────────────────────────┘
The notebook is an orchestration layer over Core. It decides what to run next (cascade planning, staleness tracking). The cell harness is an executor. Core decides whether results already exist and persists them.
uv sync --all-extras                   # Install deps (matches CI)
uv run pytest                          # Run all tests
uv run pre-commit run --all-files      # Lint + format
cd frontend && npm run dev # Frontend dev server (hot reload)Apache 2.0